Lessons from Building AutoResumeBot
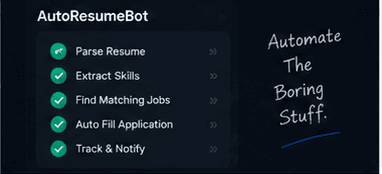
AutoResumeBot was born out of personal frustration with repetitive job application workflows. The dream was simple: upload your resume once, and let an intelligent agent handle the tailoring and submission.
However, real-world resumes are notoriously messy. Tables, multi-column designs, arbitrary date formats, and obscure fonts cause traditional regex and rule-based parsers to fail catastrophically.
I built a hybrid two-stage parsing pipeline: OCR bounding-box reconstruction followed by targeted LLM schema extraction with strict JSON validation.
The core lesson was that users value transparency above automation: giving applicants an interactive preview to verify extracted data before submission dramatically boosted user trust.
Enjoyed this article?
I write about AI engineering, backend systems, and building in public. Let's connect.
Get in touch